Unified audio editors support diverse operations, yet often struggle to modify the intended source while preserving non-target content. To strengthen this selective editing capability, we propose Source-selection Training via Early-trajectory Emphasis and Recovery (STEER), a two-stage post-training framework, and use it to develop SteerSound, a unified audio editing model supporting six common tasks.
Intermediate-state observation and bidirectional prefix interventions show that early denoising states causally influence final source selection, while incorrect early decisions often persist through subsequent denoising. Guided by these findings, STEER-Emphasis emphasizes training on task-relevant early-trajectory states to reduce source-selection errors, while STEER-Recovery learns corrective denoising from self-generated rollout states to recover from early-trajectory deviations.
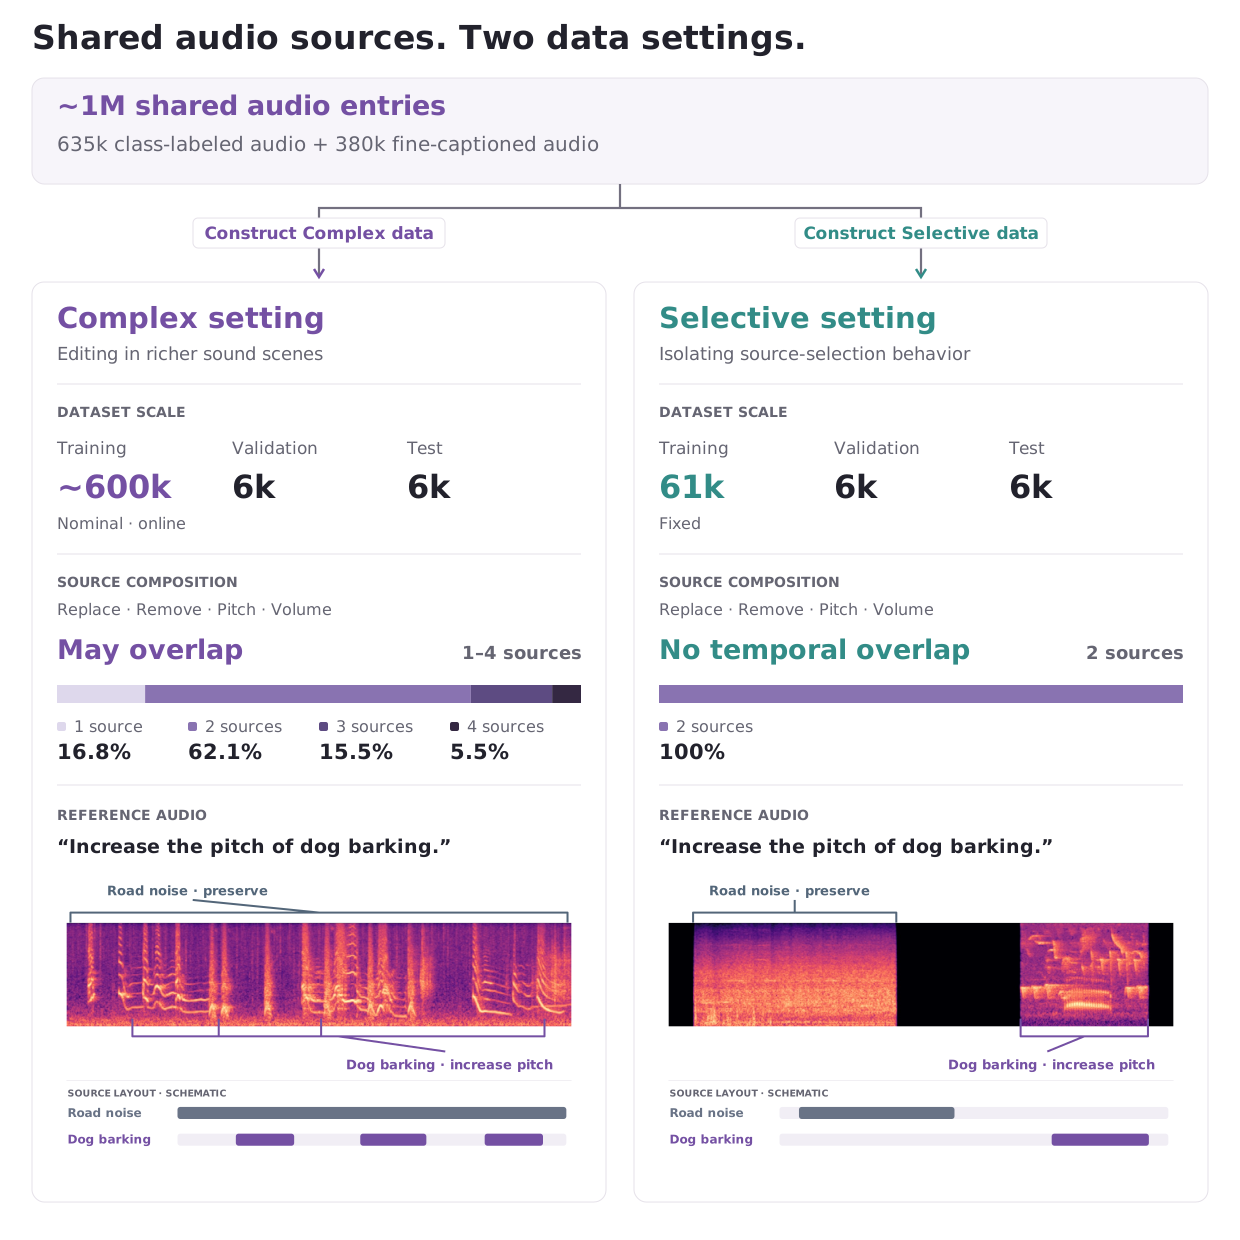
We further construct audio editing data in two complementary settings. The Selective setting enables large-scale automatic evaluation of target manipulation and non-target preservation, while the Complex setting contains richer multi-source scenes. Experiments in both settings show that STEER consistently improves selective editing reliability, reducing source-selection errors while improving overall editing performance. Further evaluations across different models and other selective-control tasks also support the broad generalizability of STEER and its underlying early-trajectory training rationale. SteerSound achieves advanced performance among open-source unified editors.
 Steer